SUPERCHARGE YOUR ONLINE VISIBILITY! CONTACT US AND LET’S ACHIEVE EXCELLENCE TOGETHER!
AI search visibility is often reported as if it were a fixed property. A brand is tested against a handful of prompts, appears in a certain percentage of responses, and the resulting number is treated as an indication of how visible that brand is across generative search.
The problem is that AI visibility can be highly dependent on how the question is asked.
A brand may appear consistently when users ask broad category questions but disappear when the same underlying need is expressed through a specific industry, commercial, geographic, competitive, or problem-based context. It may be frequently mentioned but rarely recommended, cited but poorly positioned, or visible in one type of prompt while absent from another.
This creates a measurement challenge that conventional prompt testing can overlook.
A narrow prompt set may measure visible performance without revealing the boundaries of that visibility.
That distinction is the starting point for this AVM experiment.
Instead of asking only whether a brand appears in AI-generated answers, the experiment asks a more demanding question:
Does deliberately increasing prompt diversity reveal AI visibility gaps that remain hidden when a brand is tested against a narrow set of closely related prompts?
The answer requires more than generating hundreds of random questions.
Prompt diversity needs to be structured. The experiment needs to preserve the underlying search territory while changing the ways users express their needs. It also needs to distinguish between genuine visibility gaps and normal differences in AI-generated responses.
That makes prompt diversity particularly relevant to AI Visibility Metric (AVM) analysis.
AVM can provide the measurement layer for observing brand presence, citation, prominence, recommendation and consistency across AI-generated responses. Prompt diversity, meanwhile, can expand the range of situations in which those signals are measured.
Together, they provide a way to investigate not simply how visible a brand is, but where that visibility holds, where it weakens, and under what conditions the change occurs.
Why AI Visibility Measurement Can Miss Important Gaps
Traditional search measurement generally starts with a defined query or keyword set.
A business might track:
- target keywords
- ranking positions
- search impressions
- clicks
- organic traffic
- SERP features
- conversions
The query set may be expanded over time, but the basic measurement model remains relatively straightforward.
AI search introduces a different challenge.
Users can express the same underlying need through complete questions, conversational descriptions, constraints, comparisons and contextual requests. Two prompts can have almost identical commercial intent while using substantially different language and contextual signals.
For example:
Which are the best AI SEO companies?
and:
Which agencies can help an enterprise brand improve its visibility across LLM-powered search?
These questions overlap, but they do not present exactly the same information to an AI system.
The second prompt introduces:
- enterprise context
- brand visibility
- LLM-powered search
- a specific business outcome
- an agency-selection context
A brand that appears for the first prompt may not necessarily appear for the second.
That does not automatically indicate an error.
The two prompts activate different parts of the search landscape.
However, if a business claims relevance to the second context, repeated absence becomes an observation worth investigating.
This is where a narrow visibility test can become misleading.
The problem with a “representative” prompt set
A prompt set may appear representative because it contains many questions.
But quantity does not guarantee coverage.
Consider a dataset containing these prompts:
- Best AI SEO company?
- Top AI SEO company?
- Leading AI SEO company?
- Best AI SEO agency?
- Top AI SEO agency?
- Leading AI SEO agency?
- Best AI search optimization company?
- Top AI search optimization agency?
The dataset contains eight prompts.
But semantically, the prompts occupy a relatively narrow region.
Now consider another eight prompts:
- Which AI SEO agency should an enterprise SaaS company consider?
- Who specializes in AI search optimization for ecommerce businesses?
- Which companies help brands improve visibility in AI-generated recommendations?
- What agencies focus on Generative Engine Optimization?
- Which providers combine technical SEO with AI search optimization?
- Which AI search agencies serve international businesses?
- Who can help a company that is not appearing in LLM recommendations?
- Which agencies have expertise in improving AI citation visibility?
This second set contains fewer direct synonyms but substantially more contextual variation.
The two datasets may therefore produce different pictures of the same brand.
That difference is not necessarily a contradiction.
It can be a measurement discovery.
The Problem With Narrow Prompt Sets
A narrow prompt set can produce three types of distortion.
Prompt redundancy
Multiple prompts may test essentially the same semantic condition.
Intent concentration
The test may focus heavily on one type of search intent.
Context omission
Important situations may never be tested.
For example, a brand could have excellent visibility for broad informational prompts while having limited visibility for commercial recommendations.
If the measurement system only tests informational prompts, that weakness remains invisible.
The brand may therefore appear highly visible in the report while being considerably less visible in an important segment of the actual search landscape.
This is what makes hidden AI visibility gaps important.
What Is a Hidden AI Visibility Gap?
A hidden AI visibility gap is not simply a prompt where a brand does not appear.
Absence from an irrelevant prompt is not necessarily a visibility problem.
Instead, the concept is more useful when applied to a relevant search context that was not adequately represented in the original measurement set.
For example, suppose a company provides enterprise AI search optimization.
A baseline test measures 20 broad prompts and finds the company in 16.
That produces an observed presence rate of:
16 ÷ 20 × 100 = 80%
Now expand the experiment to 100 prompts representing different relevant contexts.
Suppose the company appears in 55.
The expanded presence rate is:
55 ÷ 100 × 100 = 55%
It would be incorrect to say:
“The company’s AI visibility dropped from 80% to 55%.”
The company did not necessarily become less visible.
The two measurements sampled different prompt environments.
The more defensible interpretation is:
The original 20-prompt test captured a relatively favorable subset of the brand’s relevant search landscape, while the diversified test revealed weaker visibility in additional contexts.
That is a hidden visibility gap.
The value of the experiment lies in discovering where the gap exists.
Observed Visibility vs Latent Visibility Gaps
This distinction can be useful when interpreting AVM experiments.
Observed visibility
The visibility measured from the prompts actually tested.
Latent visibility gap
A potentially important area of relevant search where visibility has not been adequately established or where diversified testing reveals weaker performance.
The word latent is important.
Before testing, the gap may not be visible in the reporting.
It exists as a possibility within the broader search landscape.
Prompt diversification turns that possibility into something that can be investigated.
This is why prompt diversity should be viewed as a measurement-extension technique, rather than simply a prompt-generation exercise.
Why Prompt Volume Is Not the Same as Prompt Diversity
One of the easiest mistakes in AI visibility research is assuming that a larger prompt count automatically produces better measurement.
It does not.
Imagine two experiments.
Experiment A
500 prompts consisting largely of:
- best AI SEO company
- top AI SEO company
- leading AI SEO company
- best AI SEO agency
- top AI SEO agency
with minor changes to wording.
Experiment B
100 prompts covering:
- informational intent
- commercial intent
- recommendation intent
- enterprise requirements
- industry requirements
- geographic context
- competitive comparisons
- service-specific needs
- problem-based queries
- entity relationships
Experiment B may provide greater diagnostic coverage despite having one-fifth as many prompts.
The reason is simple:
Prompt count measures volume. Prompt diversity measures coverage.
A robust AVM experiment needs both sufficient volume and meaningful coverage, but the two should never be treated as interchangeable.
What Makes a Prompt Diverse?
Prompt diversity can be divided into several dimensions.
A strong experiment should deliberately control these dimensions rather than allowing them to emerge randomly.
Lexical diversity
The wording changes while the underlying intent remains similar.
For example:
Which are the best AI SEO companies?
Which are the leading AI SEO agencies?
Which firms specialize in AI search optimization?
Lexical diversity is useful, but by itself it is not enough.
Semantic diversity
The conceptual framing changes.
For example:
Which agencies provide AI SEO?
versus:
Which companies help brands become more discoverable in AI-generated answers?
The second prompt changes the conceptual description of the problem.
Intent diversity
The user objective changes.
Relevant categories can include:
- informational
- commercial investigation
- recommendation
- comparison
- transactional
- problem-solving
This dimension can reveal major visibility differences.
Audience diversity
The user profile changes.
For example:
What should a startup founder look for in an AI search optimization agency?
versus:
What should enterprise procurement evaluate when selecting an AI visibility provider?
The service category may remain similar, but the information requirements are different.
Industry diversity
The same search need is placed within different industries.
Examples include:
- SaaS
- ecommerce
- healthcare
- finance
- travel
- professional services
- technology
Industry-specific prompts test whether a brand’s associations extend beyond a generic category.
Geographic diversity
The prompt introduces location.
Examples:
Which AI SEO agencies serve businesses in India?
Which AI search optimization providers work with businesses in the UK?
Which GEO companies serve enterprise businesses in the United States?
Geographic context can change the relevant answer set.
Commercial diversity
The user’s buying situation changes.
Examples include:
- choosing a provider
- comparing providers
- finding specialists
- finding enterprise support
- evaluating alternatives
- solving an urgent visibility problem
Competitive diversity
Competitors or alternative categories are introduced.
For example:
Which AI SEO agencies should an enterprise consider?
versus:
Which agencies specialize in AI search optimization rather than conventional SEO?
The second prompt introduces a positioning distinction.
Entity diversity
The prompt changes the entities connected to the brand.
These may include:
- company
- founder
- service
- product
- technology
- industry
- location
- partner
- competitor
Entity diversity becomes particularly interesting when AVM findings are later examined through a VEM lens.
The Research Question Behind the AVM Experiment
The experiment can be expressed formally:
When the same relevant search territory is tested through increasingly diverse prompt formulations, does the measured AI visibility profile reveal gaps that are not observable in a narrow prompt set?
This question contains several smaller questions.
- Does visibility remain stable when wording changes?
- Does visibility remain stable when intent changes?
- Does commercial context alter brand recommendation?
- Does industry context alter brand presence?
- Does geography alter visibility?
- Does competitive framing change brand prominence?
- Does the brand remain cited when the prompt becomes more specific?
- Does the brand’s recommendation rate differ from its mention rate?
- Does visibility vary substantially between AI providers?
- Can the resulting patterns identify areas requiring deeper entity analysis?
These questions turn prompt testing into a structured experiment rather than an informal collection of AI searches.
The Five Hypotheses
A well-designed experiment should define its hypotheses before results are examined.
This reduces the temptation to interpret every unexpected result as meaningful.
Hypothesis 1: Narrow Prompt Sets Can Overstate Apparent Stability
If a large percentage of prompts are semantically similar, repeated brand appearances may create an impression of stable visibility.
Diversification may reveal greater variation.
The hypothesis is therefore:
A narrow prompt set may produce a more stable-looking visibility profile than a semantically diversified prompt set.
This does not mean narrow testing is invalid.
It means its findings should be understood within its sampling boundaries.
Hypothesis 2: Semantic Variation Can Reveal Context-Specific Visibility
A brand may be strongly associated with one concept but weakly associated with another related concept.
For example:
Brand → AI SEO
may be a well-established association.
But:
Brand → enterprise AI search optimization
may have weaker representation.
A diversified prompt set can test these relationships separately.
Hypothesis 3: Informational Visibility and Commercial Visibility Can Diverge
An AI system may recognize a brand while not recommending it for a purchasing decision.
Consider:
What is Generative Engine Optimization?
versus:
Which company should an enterprise hire for Generative Engine Optimization?
The first asks the AI system to provide information.
The second asks it to make or support a selection.
A brand can perform differently in those environments without the two observations being contradictory.
Hypothesis 4: Competitive Framing Can Reveal Displacement
A brand may appear when asked about a category generally.
Its visibility may change when the prompt explicitly introduces:
- competitors
- alternative services
- selection criteria
- industry specialization
- geographic requirements
This can reveal whether visibility persists under competitive constraints.
Hypothesis 5: Prompt Diversity Increases Diagnostic Coverage
The most important hypothesis is methodological.
The experiment does not need to prove that more prompts create a universally “better” score.
Instead, it tests whether prompt diversity generates more useful information about:
- where visibility occurs
- where it disappears
- which contexts produce changes
- which signals remain stable
- which signals are inconsistent
A useful measurement system should help identify patterns, not merely produce a number.
Designing the AVM Prompt Diversity Experiment
A credible experiment requires a controlled methodology.
The first step is to establish exactly what is being measured.
The target should be a defined entity and a defined search territory.
For example:
Target entity: an AI search optimization agency
Primary search territory: AI search optimization
Related territories:
- AI SEO
- GEO
- AEO
- LLM visibility
- AI discoverability
- generative search
- AI recommendations
- AI citations
These boundaries should be established before prompts are generated.
Otherwise, the experiment can become progressively broader until the prompts no longer represent the original business objective.
Step 1: Define the Target Entity and Search Territory
Before creating prompts, document:
Target entity
The brand being evaluated.
Primary category
The central service, product or market category.
Related categories
Closely connected services or concepts.
Target audiences
The audiences whose prompts matter commercially.
Target industries
Relevant verticals.
Target geographies
Markets where the brand operates or wants visibility.
Competitive environment
Relevant competitors and alternative categories.
This becomes the search-territory boundary.
Without it, prompt diversity can become prompt drift.
Step 2: Establish a Baseline Prompt Set
The baseline should reflect a conventional visibility test.
An illustrative baseline might contain 20 prompts.
For example:
- What are the best AI SEO companies?
- What are the top AI SEO agencies?
- Which companies specialize in AI SEO?
- Who provides AI search optimization?
- Which agencies offer GEO services?
- What are the leading GEO companies?
- Which companies provide LLM SEO services?
- Who are the leading AI visibility agencies?
- Which agencies specialize in generative search optimization?
- What companies help brands improve AI search visibility?
Additional prompts can expand the baseline to 20.
The important point is that these prompts should be closely related enough to establish a baseline, but not so repetitive that the dataset becomes meaningless.
The baseline is not the final answer.
It is the control condition against which diversified testing can be compared.
Step 3: Expand the Prompt Universe
The next stage introduces controlled variation.
Rather than generating prompts indiscriminately, create prompt families.
A practical structure is:
| Prompt Dimension | What It Tests |
| Lexical | Wording changes |
| Semantic | Conceptual framing |
| Intent | User objective |
| Audience | User profile |
| Industry | Business context |
| Geography | Market context |
| Commercial | Buying situation |
| Competitive | Relative positioning |
| Entity | Brand relationships |
| Problem | User need |
Each prompt should be assigned to one or more dimensions.
This makes later analysis possible.
Step 4: Create Structured Prompt Families
Prompt families allow similar questions to be evaluated together.
Consider an enterprise family.
Enterprise prompt examples
Which AI SEO agencies work with enterprise businesses?
Which companies specialize in enterprise AI search optimization?
What should a large organization look for in an AI visibility provider?
Which agencies can support AI search optimization for multinational brands?
These prompts are different.
But they belong to the same broad semantic family.
Now consider a recommendation family.
Recommendation prompt examples
Which AI SEO agency should a business consider?
Which GEO providers are suitable for an enterprise?
Which AI search optimization companies are worth evaluating?
Who specializes in improving visibility across LLM recommendations?
Grouping prompts this way prevents the analysis from treating every question as an isolated event.
Step 5: Separate Intent From Wording
This is one of the most important experimental controls.
A prompt that changes only wording should not be treated as equivalent to a prompt that changes the user’s objective.
For example:
Which agencies offer AI search optimization?
and:
Which companies provide AI search optimization?
are largely lexical variations.
But:
What is AI search optimization?
has informational intent.
And:
Which AI search optimization agency should I hire?
has commercial intent.
All three can belong in the experiment.
They should not, however, be placed into the same analytical bucket.
Intent classification allows researchers to determine whether visibility differences are associated with how the user asks or what the user is trying to accomplish.
Step 6: Introduce Commercial Context
Commercial prompts are especially valuable because they move beyond simple brand recognition.
Examples include:
Which AI search optimization agency should an ecommerce business consider?
Which GEO provider would be appropriate for an enterprise company?
What should a business evaluate before hiring an AI visibility agency?
Which AI SEO companies specialize in enterprise requirements?
Which provider should a company consider if it wants to improve AI recommendations?
For these prompts, the experiment should record more than mention.
It should determine whether the brand was:
- mentioned
- described
- cited
- recommended
- compared
- positioned prominently
- omitted
This helps distinguish recognition from recommendation.
Step 7: Introduce Industry Context
Industry context tests whether the brand’s visibility extends into specific commercial environments.
For example:
SaaS
Which agencies help SaaS companies improve visibility in AI search?
Ecommerce
Which AI search optimization companies work with ecommerce brands?
Healthcare
Which providers specialize in AI visibility for healthcare organizations?
Financial services
Which agencies help financial brands improve visibility across generative search?
These prompts should only be used where the target brand has genuine relevance to the industry.
Otherwise, absence should not be classified as a visibility failure.
That is a critical experimental principle:
A missing appearance is meaningful only when the target entity is reasonably relevant to the tested prompt.
Step 8: Introduce Audience Context
The same commercial problem can be framed differently depending on the decision-maker.
Founder-oriented prompt
What should a startup founder look for in an AI search optimization agency?
Marketing leadership
Which AI visibility providers should a CMO evaluate?
SEO team
Which agencies specialize in technical AI search optimization?
Procurement
What criteria should enterprise procurement use to evaluate AI SEO providers?
These variations test whether the brand’s AI visibility extends across different decision-making contexts.
Step 9: Introduce Geographic Context
Geographic prompts can reveal another dimension of visibility.
Examples include:
Which AI SEO agencies serve businesses in India?
Which GEO providers work with businesses in the United States?
Which AI search optimization companies serve UK businesses?
Which agencies specialize in AI visibility for European brands?
The geographic dimension should reflect actual business relevance.
Testing markets where the brand has no legitimate presence can generate misleading “gaps.”
Step 10: Introduce Competitive Context
Competitive framing can be particularly revealing.
Compare:
Which AI SEO agencies are available?
with:
Which agencies specialize in AI search optimization rather than conventional SEO?
or:
Which AI SEO providers should an enterprise compare?
or:
What alternatives to traditional SEO agencies offer AI search optimization?
The answer environment may change because the selection criteria have changed.
The target brand may remain visible.
It may move lower.
It may disappear.
Competitors may become more prominent.
Each of those outcomes provides different information.
Step 11: Introduce Problem-Based Prompts
Users often describe a problem rather than naming the service they want.
For example:
How can a business become more visible in AI-generated answers?
Who can help a brand that is not appearing in LLM recommendations?
What type of agency can improve AI citation visibility?
How can an enterprise increase its discoverability across generative search?
These prompts test whether the brand is associated with the problem it solves, rather than only with the formal name of its service.
That distinction becomes particularly important when the AVM results are later examined through entity and semantic relationships.
Establishing Experimental Controls
Prompt diversity is useful only when the experiment remains controlled.
Without controls, a diversified dataset can become so variable that its findings are impossible to interpret.
Keep the Core Search Objective Constant
The experiment should expand within a defined search territory.
A prompt about:
“What is artificial intelligence?”
should not be compared directly with:
“Which AI SEO company should an enterprise hire?”
Those questions belong to completely different search territories.
The first is general education.
The second is commercial provider selection.
They can both be studied in a larger AI-search research program, but they cannot be treated as equivalent measurements.
Avoid Artificial Prompt Diversity
Changing every word in a question does not automatically make it meaningfully diverse.
For example:
Best AI SEO agency
Best AI SEO firm
Best AI SEO company
Best AI SEO provider
may represent useful lexical variants.
But testing 100 versions of the same pattern does not create 100 independent measurements of the broader search landscape.
Prompt diversity should therefore be meaningful rather than cosmetic.
Control the AI Provider and Model Conditions
Where possible, record:
- AI provider
- model or model version
- browsing/search availability
- location
- date
- account or session conditions where relevant
- exact prompt
- conversation context
This matters because AI-generated responses are not necessarily static.
A result observed on one date may not be identical later.
Therefore, every experiment needs a time context.
Record the Exact Prompt
Do not store only a shortened keyword representation.
The exact prompt should be preserved.
This makes later analysis possible and allows researchers to determine whether an apparent visibility change was associated with:
- wording
- intent
- context
- entities
- geography
- competition
rather than relying on memory or summaries.
What Should an AVM Experiment Measure?
A prompt-diversity experiment should observe multiple dimensions of AI visibility.
A single “mentioned/not mentioned” variable is too limited for serious analysis.
ThatWare’s AVM framework provides a useful basis for evaluating AI visibility through multiple signals rather than relying solely on traditional search rankings.
For the experiment, the following observations are particularly relevant.
Brand Presence
Did the target brand appear in the answer?
This is the most basic visibility signal.
A binary record can be used:
1 = present
0 = absent
But presence should never be interpreted as the entire visibility picture.
Citation Visibility
Was the brand supported by a source or citation?
A brand can be mentioned without being cited.
That difference matters because citation and mention represent different observable properties of an AI-generated response.
Record them separately.
Recommendation Visibility
Did the AI system merely mention the brand, or did it recommend it in response to a selection-oriented prompt?
This distinction becomes particularly important for commercial searches.
A brand can have:
high mention visibility + low recommendation visibility
That is a very different situation from:
low mention visibility + low recommendation visibility.
Position and Prominence
Where did the brand appear?
A brand appearing first in a recommendation list and a brand appearing as an incidental mention near the end are both “present,” but they do not represent the same degree of prominence.
Record position wherever the response structure makes this possible.
Consistency
Does the brand appear across related prompt variants?
This is where prompt diversity becomes especially powerful.
Instead of asking:
Did the brand appear?
the experiment asks:
Did the brand continue to appear when the prompt changed within the same relevant search family?
Cross-Provider Visibility
If the experiment is run across multiple AI systems, compare the patterns carefully.
The purpose is not to declare one provider universally better.
Instead, ask:
Does the target brand exhibit the same visibility pattern across different AI environments?
A brand may show high visibility in one environment and substantially different visibility in another.
That divergence is itself a measurable observation.
Measuring Prompt-Level AI Visibility
Aggregate scores are useful for reporting.
Prompt-level data is useful for diagnosis.
That is why the experiment should preserve the underlying observations.
Presence Rate
A simple experimental measure is:
Presence Rate = Number of relevant prompts containing the brand ÷ Total relevant prompts × 100
For example:
- 100 relevant prompts tested
- brand appears in 62
Presence rate:
62%
This provides a basic measure of observed coverage.
But it does not reveal where the remaining 38% occurs.
That requires prompt-family analysis.
Citation Rate
A simple research metric can be:
Citation Rate = Cited brand appearances ÷ Total brand appearances × 100
For example:
- brand appears 60 times
- cited 35 times
Citation rate:
58.3%
This can help distinguish visibility from evidentiary support.
However, any such derived metric should be clearly labeled as an experimental analytical measure, not presented as an official AVM formula unless it is documented as such.
Recommendation Rate
For prompts where provider selection is the intended outcome:
Recommendation Rate = Recommended appearances ÷ Relevant recommendation prompts × 100
This metric can expose a commercially important gap.
A brand may have strong general visibility but weak recommendation visibility.
Position Distribution
Rather than assigning every response a single position score, researchers can record the distribution.
For example:
- first position
- second position
- third position
- lower-list appearance
- unranked mention
- incidental mention
- absent
This preserves more information than a simple binary variable.
Prompt Stability
Prompt stability examines whether visibility persists across closely related questions.
Suppose five prompts represent the same commercial intent.
The brand appears in:
5/5
That family demonstrates strong observed consistency.
Another family produces:
2/5
The second family represents a potential visibility gap.
The comparison becomes more useful than an overall score because it tells the analyst which part of the search landscape is unstable.
Visibility Variance
The experiment can also examine how much visibility changes across prompt families.
A brand may have:
- high general visibility
- moderate commercial visibility
- low enterprise visibility
- high geographic visibility
- low competitive visibility
The variation itself becomes an important research observation.
The Prompt Diversity Matrix
At this point, the experiment can be represented as a matrix rather than a flat keyword list.
| Dimension | Example |
| Intent | Informational |
| Intent | Commercial |
| Intent | Comparative |
| Audience | Founder |
| Audience | CMO |
| Audience | SEO Manager |
| Industry | SaaS |
| Industry | Ecommerce |
| Geography | India |
| Geography | UK |
| Service | GEO |
| Service | Answer Engine Optimization |
| Problem | AI discoverability |
| Problem | AI recommendation |
| Competition | Alternative providers |
| Entity | Brand + service |
| Entity | Brand + founder |
| Entity | Brand + location |
This structure allows the experiment to answer a much more valuable question than:
“How many times was the brand mentioned?”
It can answer:
“Which combinations of intent, context and entity relationships produce or suppress brand visibility?”
That is the beginning of meaningful AI visibility diagnostics.
Building the Expanded Prompt Test Set
Once a baseline prompt set has been established, the next stage is to deliberately expand the search environment.
The objective is not to create as many prompts as possible. It is to create enough meaningfully different prompts to test whether the target brand’s AI visibility persists across the relevant dimensions of search intent.
For a practical AVM experiment, an expanded dataset can be organized into three levels:
| Testing layer | Illustrative size | Primary purpose |
| Baseline | 10–20 prompts | Establish initial visibility |
| Diagnostic | 50–100 prompts | Identify contextual gaps |
| Research/enterprise | 100–500+ prompts | Study broader visibility patterns |
These are experimental planning ranges, not a universal AVM requirement.
The appropriate sample depends on the size and complexity of the search territory.
A single-product business operating in one market may require fewer prompt families than an enterprise brand with multiple products, industries and geographic markets.
The important principle is consistency: define the sampling methodology before interpreting the results.
Creating a 50–100 Prompt Diagnostic Dataset
A useful diagnostic dataset should deliberately distribute prompts across multiple dimensions.
For example, a 100-prompt experiment could be structured approximately as follows:
| Prompt category | Example allocation |
| General category | 10 |
| Informational | 10 |
| Commercial | 15 |
| Recommendation | 10 |
| Service-specific | 10 |
| Industry-specific | 10 |
| Enterprise | 10 |
| Geographic | 10 |
| Competitive | 10 |
| Problem-based | 5 |
| Total | 100 |
The allocation does not need to be identical for every business.
A healthcare company, for example, may need more healthcare-specific prompts.
An international enterprise may need a much larger geographic component.
The table illustrates the principle of balanced coverage rather than random prompt expansion.
Why Prompt Families Are More Useful Than a Flat Prompt List
A flat list tells you what happened.
Prompt families can help explain where it happened.
Suppose a brand appears in 60 out of 100 prompts.
An aggregate presence rate of 60% tells you something.
But consider the following breakdown:
| Prompt family | Brand appearances | Prompts | Presence |
| General | 9 | 10 | 90% |
| Informational | 8 | 10 | 80% |
| Commercial | 6 | 15 | 40% |
| Recommendation | 7 | 10 | 70% |
| Enterprise | 3 | 10 | 30% |
| Industry | 7 | 10 | 70% |
| Geographic | 8 | 10 | 80% |
| Competitive | 4 | 10 | 40% |
| Service-specific | 6 | 10 | 60% |
| Problem-based | 2 | 5 | 40% |
The overall number hides a much more interesting pattern.
The brand appears highly visible in broad and informational contexts, but visibility becomes substantially weaker in enterprise and competitive contexts.
That is the kind of finding prompt diversity can uncover.
Separating Baseline Prompts From Diagnostic Prompts
The baseline and diagnostic sets should not be mixed conceptually.
The baseline answers:
How does the brand perform under conventional, relatively concentrated testing?
The diagnostic set asks:
How does that performance change when relevant contextual dimensions are introduced?
This distinction prevents the experiment from becoming a simple before-and-after score comparison.
The objective is to identify distributional differences.
The Three-Layer Prompt Architecture
A useful approach is to construct prompts in three layers.
Core layer
These are stable prompts that remain unchanged between measurement cycles.
They create the longitudinal baseline.
Expansion layer
These prompts cover additional search contexts.
They can be refreshed periodically while maintaining the same classification framework.
Stress-test layer
These deliberately test difficult or less obvious formulations.
Examples include:
- indirect descriptions
- ambiguous terminology
- competitor comparisons
- highly specific requirements
- unusual but relevant wording
- multi-condition questions
This layered structure prevents every new prompt from changing the measurement baseline.
Understanding the First Experimental Comparison
Consider a hypothetical brand.
The baseline consists of 20 prompts.
The brand appears in 16.
Baseline observed presence = 80%
The diagnostic set adds 80 prompts.
Across all 100 prompts, the brand appears in 58.
Expanded observed presence = 58%
The immediate temptation is to say:
“Prompt diversity reduced AI visibility from 80% to 58%.”
That conclusion is incorrect.
The brand’s visibility did not necessarily change.
The sample changed.
The correct observation is:
The brand demonstrated 80% presence within the narrow baseline sample and 58% presence across the broader diversified sample.
The next question is:
What additional prompts produced the difference?
That is where the experiment becomes useful.
Decomposing the Difference
Suppose the additional 80 prompts produced the following results:
- 10 general prompts → 9 appearances
- 10 informational prompts → 8 appearances
- 15 commercial prompts → 7 appearances
- 10 enterprise prompts → 3 appearances
- 10 competitive prompts → 4 appearances
- 10 geographic prompts → 8 appearances
- 10 service-specific prompts → 7 appearances
- 5 problem-based prompts → 3 appearances
The results immediately identify several areas for investigation.
The weakest observed categories are:
- enterprise
- competitive
- commercial
- problem-based
The experiment has therefore done something the original baseline could not do.
It has identified specific contextual conditions associated with lower observed visibility.
The First Hidden Gap: Intent Visibility
Search intent is one of the most important dimensions to test.
A brand can be visible when users ask for information but less visible when users ask for a recommendation.
Consider three prompt families.
Informational
What is Generative Engine Optimization?
Commercial investigation
Which companies provide Generative Engine Optimization?
Recommendation
Which GEO agency should an enterprise consider?
The target brand may appear consistently in the first family and inconsistently in the second and third.
That pattern can be described as an intent visibility gap.
It does not necessarily mean the brand lacks authority.
It means the brand’s observed AI visibility differs according to the user’s objective.
Why Informational Visibility Can Create a False Sense of Coverage
Informational prompts are often easier to scale because they cover broad educational questions.
A brand might be associated with a topic and therefore appear in explanations of that topic.
But a recommendation prompt introduces additional requirements.
The AI system may need to identify:
- relevant providers
- business suitability
- specialization
- geography
- industry expertise
- comparative attributes
- evidence
- potentially competing entities
Consequently, informational presence should not be treated as equivalent to commercial recommendation visibility.
A diversified experiment makes that distinction measurable.
The Second Hidden Gap: Category Visibility
Another pattern appears when the target brand is visible for its primary category but less visible for related services.
For example:
Primary category:
AI SEO
Related categories:
- GEO
- AEO
- LLM SEO
- AI visibility
- AI search optimization
- semantic search optimization
A brand may be strongly associated with AI SEO but appear less frequently when users use another relevant category label.
This creates a potential category visibility gap.
The gap becomes particularly interesting when the business actually provides the relevant service.
Category Expansion Should Be Controlled
Category expansion must be based on genuine semantic relationships.
It should not be used to manufacture visibility gaps by testing unrelated topics.
For example, if an AI SEO agency does not provide web hosting, the absence of that agency from:
“Which web hosting companies should I consider?”
is not a meaningful visibility gap.
The experimental rule should therefore be:
Only classify absence as diagnostically relevant when the target entity has legitimate relevance to the prompt.
This simple rule protects the experiment from producing artificial conclusions.
The Third Hidden Gap: Recommendation Visibility
Mention and recommendation are not interchangeable.
Suppose an AI response says:
“Company X provides AI search optimization. Other providers include Company Y and Company Z.”
Company X has achieved presence.
But suppose another response says:
“For an enterprise looking for AI search optimization, Company X would be one provider to consider.”
That response provides a stronger recommendation signal.
Now imagine a third answer:
“The most suitable providers for this requirement include Company Y and Company Z.”
If Company X is mentioned only as background information, its presence does not mean that it is competing equally for the recommendation.
This is why recommendation prompts should be separately analyzed.
Mention Rate vs Recommendation Rate
An experimental dataset could contain:
- 100 relevant prompts
- 65 brand mentions
- 30 recommendations
The results could be expressed as:
Presence rate = 65%
Recommendation rate = 30%
These figures answer different questions.
Presence asks:
Does the AI system include the brand?
Recommendation asks:
Does the AI system position the brand as an option relevant to the user’s decision?
A business interested in commercial AI visibility needs to understand both.
The Fourth Hidden Gap: Citation Visibility
A similar distinction applies to citations.
A brand can be mentioned without the response providing a supporting source associated with that brand.
That means:
Mention ≠ Citation
An AVM experiment can therefore record both.
For example:
| Observation | Count |
| Relevant prompts | 100 |
| Brand mentioned | 60 |
| Brand cited | 34 |
| Brand recommended | 29 |
This creates several different visibility layers.
A brand may have:
- broad presence
- moderate citation visibility
- lower recommendation visibility
That pattern is considerably more informative than a single 60% visibility figure.
The Fifth Hidden Gap: Position
Position is another dimension that aggregate presence can hide.
Suppose an AI system provides a list of ten companies.
The target brand appears in position two for some prompts and position nine for others.
Both observations are technically “present.”
But they represent different degrees of prominence.
A diversified test should therefore capture position where the answer structure allows it.
Possible categories include:
- first position
- upper positions
- middle positions
- lower positions
- unranked mention
- incidental mention
- absent
This allows the experiment to distinguish presence from prominence.
The Sixth Hidden Gap: Competitive Visibility
Competitive prompts are particularly valuable because AI recommendations rarely exist in isolation.
A user may ask:
Which AI SEO companies should I consider?
The answer environment may change substantially when the prompt becomes:
Which AI SEO companies should an enterprise compare?
or:
Which AI search optimization providers are alternatives to conventional SEO agencies?
or:
Compare AI SEO providers for a company looking to improve generative search visibility.
These prompts introduce a competitive frame.
The target brand’s appearance can then be compared with the appearance and positioning of other entities.
Measuring Competitive Displacement
Suppose the target brand appears in 70% of open-category prompts.
When competitors are explicitly introduced, it appears in 42%.
That difference does not prove that competitors caused the reduction.
But it establishes an important observation:
The target brand’s observed visibility is lower in competitive prompt contexts than in open-category contexts.
Further investigation can then determine whether the difference is associated with:
- competitor entities
- industry context
- selection criteria
- service terminology
- entity relationships
- provider-specific retrieval patterns
The key is to treat the observation as a starting point for analysis rather than a causal conclusion.
The Seventh Hidden Gap: Geographic Visibility
A brand can also have uneven visibility by geography.
For example:
| Geography | Presence |
| Global/general | 75% |
| India | 80% |
| United States | 60% |
| United Kingdom | 50% |
| Europe | 45% |
These numbers are illustrative.
They do not mean that the brand should necessarily achieve identical visibility in every market.
Geographic prompts should be interpreted according to the brand’s actual operations and relevance.
If a company actively serves a market but repeatedly disappears from relevant prompts for that market, however, the pattern may warrant investigation.
The Eighth Hidden Gap: Industry Visibility
Industry prompts create another layer.
A business may have strong general AI visibility but weaker visibility when a particular industry is specified.
For example:
| Industry | Observed presence |
| General | 80% |
| SaaS | 75% |
| Ecommerce | 65% |
| Healthcare | 40% |
| Finance | 35% |
Again, the numbers are illustrative.
The important insight is the distribution.
A business may discover that its strongest AI associations are concentrated around a particular industry.
That can be valuable even when the overall visibility score appears strong.
The Ninth Hidden Gap: Audience Visibility
Prompt diversity can also test whether different decision-maker contexts produce different results.
Consider:
Founder
Which AI search optimization agency should a startup founder consider?
CMO
Which AI visibility providers should a marketing leader evaluate?
SEO manager
Which agencies specialize in technical AI search optimization?
Procurement
What should enterprise procurement evaluate when selecting an AI SEO provider?
If the brand appears primarily in founder-oriented prompts but less frequently in enterprise procurement prompts, the experiment has identified an audience-context difference.
This can then be investigated independently.
The Tenth Hidden Gap: Problem-to-Entity Visibility
Problem-based prompts provide a particularly interesting test.
Users may not know the technical term for a service.
Instead, they describe the problem.
For example:
Why is my brand not appearing in AI-generated answers?
How can a company increase its visibility in LLM recommendations?
Why does AI mention my competitors but not my company?
How can a business improve its presence in generative search?
These prompts test whether the brand is associated with the problem domain, rather than merely with a service label.
A business may rank strongly within service terminology but have limited visibility when users describe the underlying problem.
That creates another potentially valuable diagnostic signal.
Measuring Prompt Sensitivity
The preceding sections lead to one of the experiment’s most important concepts:
prompt sensitivity.
Prompt sensitivity describes how much observed AI visibility changes when the prompt changes.
The change can occur across:
- wording
- intent
- context
- entities
- geography
- competition
- industry
- audience
The goal is not to eliminate all sensitivity.
AI systems are expected to respond differently to different questions.
The goal is to understand where sensitivity becomes significant.
Low Prompt Sensitivity
Imagine ten related prompts.
The brand appears in:
9, 9, 8, 9, 9, 8, 9, 9, 8, 9.
The observed visibility pattern is relatively stable.
High Prompt Sensitivity
Now consider:
9, 8, 2, 7, 1, 8, 3, 9, 2, 7.
The brand remains visible in some prompts but disappears in others.
The important question becomes:
What changed between the prompts where visibility was strong and those where it was weak?
That is precisely what prompt-family analysis can uncover.
Why Prompt Sensitivity Is Not Automatically a Problem
A high degree of variation does not necessarily indicate poor optimization.
Suppose:
Which AI SEO agencies operate in India?
and:
Which AI SEO agencies specialize in Japanese-language ecommerce?
These questions have different contextual requirements.
A different answer set may be entirely reasonable.
Therefore, the experiment must distinguish between:
expected variation
and
unexpected visibility gaps.
A gap becomes more interesting when:
- the target entity is clearly relevant;
- the prompts belong to a related search territory;
- the variation is systematic rather than isolated;
- similar prompts repeatedly produce the same pattern;
- the difference cannot easily be explained by prompt irrelevance.
Prompt Family Consistency
One of the strongest ways to investigate this is to examine family-level consistency.
Suppose there are ten commercial prompts.
The brand appears in eight.
Then ten enterprise prompts are tested.
The brand appears in three.
This creates a useful contrast.
Rather than reporting:
“The brand has 55% visibility.”
the experiment can say:
“Observed visibility was substantially stronger in the commercial baseline family than in the enterprise-specific family.”
The second statement contains considerably more diagnostic information.
The Prompt Diversity Gap
The concept can now be formalized.
A Prompt Diversity Gap can be used as an experimental descriptor for the difference between visibility observed in a narrow baseline sample and visibility observed across a broader, controlled prompt sample.
A simple representation is:
Prompt Diversity Gap = Baseline observed visibility − Diversified observed visibility
Suppose:
Baseline = 80%
Diversified = 60%
Then:
Prompt Diversity Gap = 20 percentage points
This does not mean the brand “lost” 20 points of visibility.
It means the expanded test exposed a 20-point difference between the two observed measurement environments.
That distinction should always accompany the metric.
Why the Prompt Diversity Gap Is Diagnostic Rather Than Definitive
The gap itself does not explain its cause.
A large difference could arise from:
- baseline prompt concentration
- additional search intents
- new industry contexts
- geographic variation
- competitive framing
- model behavior
- sampling differences
- prompt irrelevance
- entity ambiguity
Therefore, the Prompt Diversity Gap should trigger diagnostic analysis, not automatic optimization.
An Illustrative AVM Experiment Dataset
To make the methodology concrete, consider an entirely illustrative 100-prompt dataset.
The target brand is relevant to all 100 prompts.
Baseline set
20 prompts.
Brand appears in:
16
Observed presence:
80%
Expanded set
80 additional prompts.
Brand appears in:
44
Observed presence:
55%
Combined dataset
100 prompts.
Brand appears in:
60
Observed presence:
60%
The first result looks strong.
The combined result looks substantially different.
But the interesting information is contained in the additional 80 prompts.
Suppose they produce:
| Prompt family | Prompts | Brand appearances | Presence |
| Informational | 10 | 8 | 80% |
| Commercial | 15 | 7 | 47% |
| Enterprise | 10 | 3 | 30% |
| Geographic | 10 | 8 | 80% |
| Competitive | 10 | 4 | 40% |
| Service-specific | 10 | 6 | 60% |
| Industry | 10 | 6 | 60% |
| Problem-based | 5 | 2 | 40% |
| Total | 80 | 44 | 55% |
The experiment now reveals a pattern.
The brand’s visibility is not uniformly distributed.
It is relatively strong in:
- informational
- geographic
and weaker in:
- enterprise
- competitive
- problem-based
- commercial
That is far more useful than knowing only that the combined presence rate is 60%.
What the Illustrative Dataset Does Not Prove
The dataset above is deliberately illustrative.
It does not demonstrate that a particular brand actually has these visibility rates.
It demonstrates how a real experiment can be analyzed.
This distinction is essential for responsible AI-search research.
A publishable ThatWare case study should replace illustrative values with:
- actual prompt counts
- actual responses
- actual providers
- actual dates
- actual observations
- actual AVM measurements
where those data are available.
If real data are unavailable, the article should clearly label examples as hypothetical or illustrative.
Detecting Whether a Gap Is Real
Once a potential gap is discovered, the next task is validation.
A single missing response should rarely be treated as a meaningful pattern.
The first question is:
Does the gap repeat?
Suppose the brand disappears from one enterprise prompt.
That is an observation.
Suppose it appears in only 2 of 15 enterprise prompts.
That is a stronger pattern.
Suppose the same pattern occurs across repeated testing and multiple relevant enterprise formulations.
Now the gap becomes substantially more interesting.
Replication Within a Prompt Family
Replication can be performed by creating additional prompts within the same family.
For example:
Original enterprise prompt
Which AI search optimization companies work with enterprise businesses?
Replication 1
Which AI SEO agencies specialize in large enterprise organizations?
Replication 2
Which providers offer enterprise-level AI visibility services?
Replication 3
Which agencies can support multinational companies with AI search optimization?
If the same visibility pattern persists, the evidence for a contextual gap becomes stronger.
Distinguishing a Genuine Gap From Prompt Irrelevance
The relevance test should happen before the optimization test.
Ask:
Is the brand actually relevant?
Does it offer the service?
Does it serve the industry?
Does it operate in the geography?
Does it target the audience?
Does it legitimately compete in the category?
If the answer is no, absence is not a useful visibility gap.
This protects the experiment from a common analytical error:
turning every non-appearance into a problem.
Distinguishing a Gap From Random AI Variation
AI-generated responses can vary.
Therefore, one run is rarely sufficient to establish a stable behavioral pattern.
Where the experimental setup allows it, researchers should repeat selected prompts and observe:
- repeated presence
- repeated absence
- position changes
- citation changes
- recommendation changes
- competitor changes
The purpose is to identify patterns rather than isolated outputs.
Cross-Provider Differences
A diversified experiment can also be repeated across different AI environments.
For example:
- Provider A
- Provider B
- Provider C
- Provider D
The objective is not to declare one platform superior.
Instead, examine whether the target brand’s visibility pattern is consistent.
Imagine:
| Provider | Overall presence | Enterprise presence | Commercial presence |
| Provider A | 70% | 60% | 65% |
| Provider B | 55% | 30% | 45% |
| Provider C | 65% | 50% | 40% |
| Provider D | 40% | 25% | 35% |
The pattern suggests that the same brand does not necessarily have identical visibility across AI environments.
That finding is important for AVM analysis because a single-provider measurement can hide provider-specific visibility differences.
Why Provider-Level Analysis Matters
Different AI systems can have different:
- retrieval mechanisms
- model architectures
- source ecosystems
- update cycles
- browsing behavior
- response-generation patterns
Therefore, an experiment should record the provider and model conditions wherever possible.
The question should be:
Is the visibility pattern consistent across the tested environments?
rather than:
Which provider gives the “correct” result?
The experiment is measuring observable AI-search behavior, not accessing proprietary internal ranking logic.
From AVM Observation to VEM Investigation
Prompt diversity tells us where visibility changes.
It does not automatically explain why.
This is where VEM can become relevant.
Suppose the experiment identifies the following pattern:
Strong visibility:
AI SEO
Weak visibility:
Enterprise AI search optimization
The next analytical question is whether the brand has sufficiently strong semantic relationships connecting:
Brand → Enterprise → AI Search → Optimization → Business Outcome
If those relationships are weak, fragmented or inconsistently represented across relevant sources, the observation can become a candidate for VEM investigation.
The process therefore becomes:
Prompt diversity → AVM observation → visibility gap → entity investigation
rather than:
Prompt diversity → assumed cause
That separation is important.
AVM Detects the Pattern; VEM Investigates the Entity Context
The two frameworks can therefore serve complementary analytical functions.
AVM-oriented question
Where and how often does the brand appear?
VEM-oriented question
What entity and semantic relationships may be relevant to the contexts where the brand is or is not being recognized?
This does not mean every AVM gap is caused by a VEM issue.
Other factors may include:
- retrieval behavior
- source availability
- competitor signals
- prompt construction
- model differences
- temporal changes
- geographic context
VEM should therefore be used as an investigative layer, not a universal explanation.
Looking for Entity-Context Gaps
Suppose a brand is strongly associated with:
AI SEO
but weakly associated with:
AI SEO + healthcare
The experiment can then inspect whether relevant entity relationships exist around:
- brand
- healthcare
- AI SEO
- healthcare search
- compliance-related context
- relevant expertise
- case evidence
- geographic relevance
The objective is not to force the AI system to produce a particular answer.
It is to determine whether the brand’s externally observable entity context adequately represents the relevance it claims.
Entity Relationships and Prompt Activation
Different prompts can activate different semantic neighborhoods.
A broad prompt may activate:
Brand → Service
A more specific prompt may activate:
Brand → Service → Industry → Audience → Geography
The more relationships required to produce a relevant answer, the more complex the entity context becomes.
This provides a useful way to interpret prompt-diversity findings.
If visibility weakens as contextual specificity increases, researchers can investigate whether the brand’s semantic representation becomes less complete at those deeper levels.
Again, this is an investigation path rather than proof of causation.
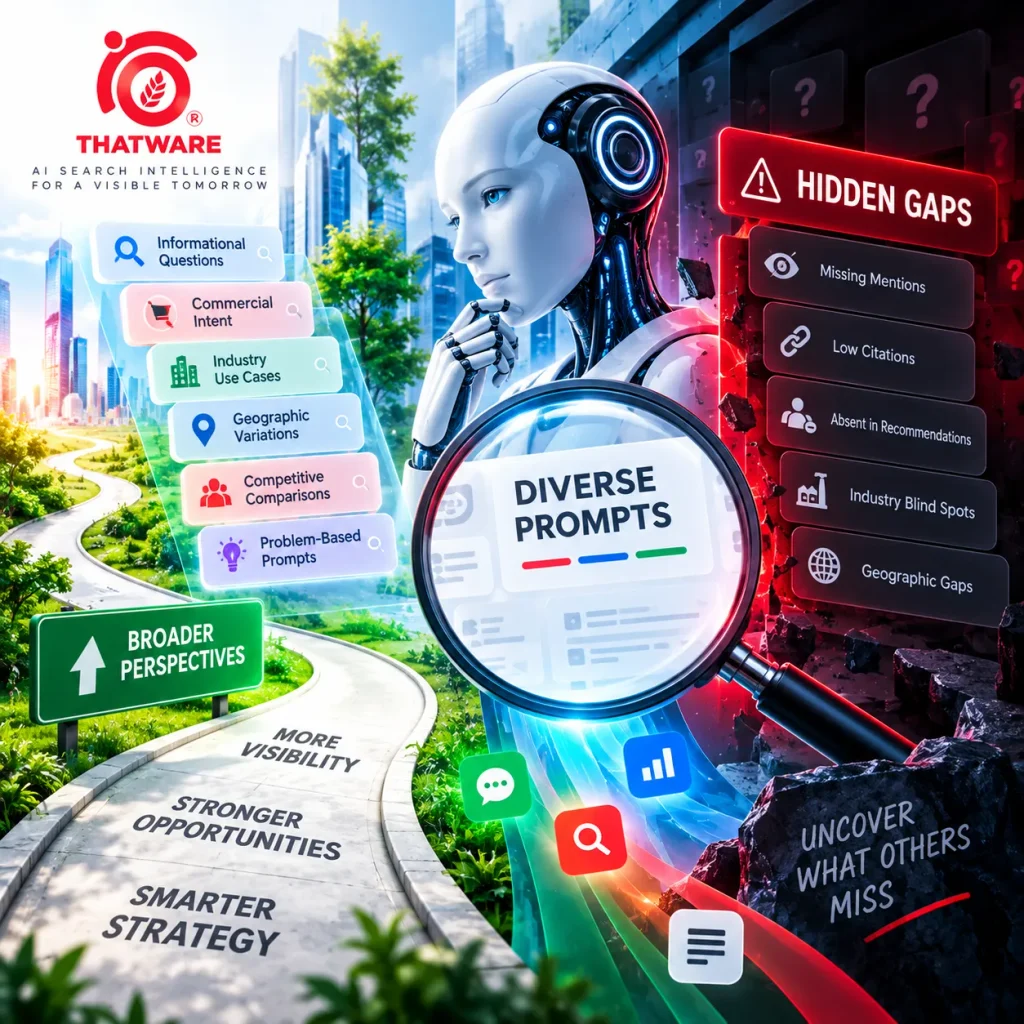
The AVM–VEM Diagnostic Loop
The complete analytical process can therefore be represented as:
Prompt Diversity
↓
Broader Search Sampling
↓
AVM Visibility Measurement
↓
Prompt-Family Comparison
↓
Hidden Gap Detection
↓
Pattern Validation
↓
VEM Entity Investigation
↓
Optimization Hypothesis
↓
Retesting
The loop is important because AI visibility measurement should not stop at identifying a gap.
The gap should lead to a testable hypothesis.
That hypothesis should lead to an intervention.
The intervention should then be evaluated through another measurement cycle.
The Most Important Analytical Principle
The strongest conclusion from this stage of the experiment is not:
“More prompts produce a better AVM score.”
That would be too broad.
The more defensible conclusion is:
Controlled prompt diversity can increase the diagnostic coverage of AI visibility measurement by exposing differences across relevant search contexts that may remain hidden in a narrow prompt set.
That is a more precise claim.
It also leaves room for the realities of AI search:
- responses can vary
- models change
- retrieval environments differ
- prompts have different intents
- not every absence is a gap
- visibility does not imply recommendation
- correlation does not establish causation
A strong AVM experiment needs to account for all of these factors.
Interpreting AI Visibility Gaps Without Overclaiming
The hardest part of an AI visibility experiment is often not collecting the responses. It is interpreting them correctly.
A diversified prompt set can uncover differences that a narrow test never exposed, but those differences should not automatically be described as failures, ranking losses, algorithmic penalties or evidence of a specific optimization problem.
AI-generated responses are influenced by multiple variables, and an observational experiment usually cannot isolate every causal factor.
The correct approach is therefore to move through a sequence:
Observation → Classification → Validation → Investigation → Hypothesis → Optimization → Retest
For example:
“The brand appeared in 82% of general prompts but 41% of enterprise prompts.”
That is an observation.
“The brand has an enterprise AI visibility gap.”
That is an interpretation.
“The gap exists because the brand lacks enterprise entity signals.”
That is a causal hypothesis.
Those three statements should not be treated as equivalent.
A rigorous AVM experiment keeps them separate.
Observation Is Not Causation
Suppose a brand disappears from several prompts containing the term “enterprise.”
There may be several explanations:
- the model retrieved different sources
- competitors had stronger associations with enterprise terminology
- the prompt introduced additional selection criteria
- the brand’s website contains limited enterprise-specific information
- third-party sources associate the brand less strongly with enterprise services
- the model interpreted the prompt differently
- the response was simply variable
- the test conditions changed
The experiment can identify the pattern.
It cannot automatically identify the cause.
That is why the next stage should involve deeper analysis.
Validating a Suspected Visibility Gap
Once a potential gap appears, validate it before treating it as strategically significant.
A useful validation process has five stages.
Relevance
Is the brand genuinely relevant to the prompt?
Repetition
Does the pattern occur more than once?
Family consistency
Does the same pattern appear across related prompts?
Context consistency
Does it persist when wording changes but the underlying intent remains similar?
Temporal consistency
Does the observation persist when the test is repeated at a later point?
The more conditions a pattern survives, the more useful it becomes as an investigation target.
Relevance Validation
The first question should always be:
Should the brand reasonably be expected to appear here?
For example, if a company does not provide a particular service, its absence from prompts requesting that service is not a visibility gap.
Similarly, if a business does not operate in a specific country, absence from a location-specific provider query may be expected.
Prompt diversity should therefore be bounded by business relevance.
This prevents the experiment from becoming a search for artificial weaknesses.
Repetition Validation
A single response is weak evidence of a persistent pattern.
Suppose:
Prompt A → brand absent
That is one observation.
Now test:
Prompt B → brand absent
Prompt C → brand absent
Prompt D → brand absent
If all four prompts represent the same relevant intent, the pattern becomes more interesting.
Repeated observations do not automatically prove causation, but they provide stronger evidence that the result is not simply an isolated response.
Prompt-Family Validation
The strongest validation occurs when the same pattern persists across a family of semantically related prompts.
For example:
Enterprise family
Which AI SEO agencies work with enterprise companies?
Which AI search optimization providers specialize in enterprise brands?
Which GEO agencies support large organizations?
Which AI visibility providers serve multinational businesses?
If the target brand appears in only one of four prompts, that pattern is more meaningful than a single isolated absence.
The experiment can now investigate enterprise-context visibility.
Separating Genuine Gaps From Measurement Artifacts
Not every difference revealed by prompt diversity is a genuine business problem.
Several artifacts can distort the results.
Prompt Irrelevance
The target brand may not actually be relevant.
Prompt Redundancy
The baseline may contain many nearly identical prompts.
Sample Imbalance
One category may contain 50 prompts while another contains only five.
Provider Variation
Different AI systems may produce substantially different outputs.
Model Updates
A model or retrieval system can change between test cycles.
Temporal Variation
The same prompt can produce different results at different times.
Geographic Variation
Location can affect what entities are considered relevant.
Context Contamination
Previous conversational turns may influence the response.
Citation Availability
A brand may be mentioned even when the system has no accessible source to cite.
Each of these factors should be documented.
Prompt Diversity Needs a Relevance Boundary
A useful experimental rule is:
Diversify within the search territory, not beyond it.
Imagine the target entity is an AI search optimization provider.
Valid diversification could include:
- AI SEO
- GEO
- AI visibility
- LLM visibility
- AI recommendations
- enterprise AI search
- AI citations
- generative search
But completely unrelated topics should not be introduced merely because they produce a different answer.
This is similar to experimental sampling in other disciplines.
The sample needs to represent the population being studied.
If the search territory changes, the measurement objective changes with it.
Building an AI Visibility Test Suite
Once prompt diversity has demonstrated its diagnostic value, the next step is to turn the experiment into a repeatable process.
Instead of rebuilding the prompt set from scratch every time, create an AI visibility test suite.
The suite should contain several layers.
Core Prompts
These remain stable.
They provide longitudinal comparability.
For example:
- 20–30 high-priority prompts
- fixed wording
- fixed intent
- fixed classification
The core set can be tested regularly.
Expansion Prompts
These provide broader coverage.
They can include:
- new semantic variations
- new user contexts
- new industries
- new commercial scenarios
- new locations
- emerging terminology
The expansion set allows the experiment to evolve without destroying the stable baseline.
Stress-Test Prompts
Stress prompts deliberately test difficult situations.
Examples include:
Which providers specialize in a very specific use case?
Which agencies offer an alternative to conventional SEO?
Which company would be suitable for a multinational organization with multiple markets?
These prompts test whether visibility survives increased contextual complexity.
Competitive Prompts
Competitive prompts examine how the target brand behaves when other entities are explicitly part of the search context.
These can include:
- comparison
- alternatives
- category selection
- specialist selection
- enterprise procurement
- competitor-specific prompts
The objective is to observe competitive visibility, not to manufacture a winner.
Entity Prompts
Entity prompts connect the brand to relevant entities.
For example:
Brand + service
Brand + founder
Brand + location
Brand + industry
Brand + technology
Brand + expertise
These prompts can help identify whether the brand’s visibility changes when additional semantic relationships become important.
Prompt Diversity as AI Visibility Regression Testing
One of the most practical applications of the methodology is regression testing.
Software teams use regression tests to determine whether a change has unexpectedly affected existing functionality.
AI search teams can apply a similar principle to visibility monitoring.
A stable prompt suite can be run before and after important changes.
For example:
Website migration
Brand repositioning
Service launch
Major content update
Navigation restructuring
Rebranding
Acquisition
New market expansion
The objective is to compare observations under consistent conditions.
Testing After a Website Migration
A migration can alter:
- URLs
- content relationships
- internal linking
- structured information
- page hierarchy
- service descriptions
Rather than waiting for traditional search metrics to reveal problems, a business can rerun its AI visibility test suite.
The important question becomes:
Did the observable AI visibility pattern change after the migration?
If it did, further investigation can determine which prompt families changed.
Testing After a Rebrand
A rebrand can change:
- company name
- descriptions
- service terminology
- domain
- organizational relationships
- third-party references
An AI visibility test can examine whether the new identity continues to be associated with the relevant services and entities.
This is particularly relevant to VEM-oriented analysis.
Testing After Launching a New Service
Suppose a company launches a new AI search service.
A conventional SEO campaign may target the new service term.
An AI visibility experiment can additionally test whether AI systems associate:
Brand → New Service
and whether that association appears across relevant prompts.
This can include:
- informational prompts
- commercial prompts
- recommendation prompts
- industry prompts
- comparison prompts
The objective is to monitor the development of the new semantic association.
Longitudinal AI Visibility Measurement
A single experiment provides a snapshot.
Repeated experiments provide a trajectory.
Consider:
| Month | General | Commercial | Enterprise | Competitive |
| Month 1 | 80% | 55% | 35% | 40% |
| Month 2 | 82% | 58% | 40% | 43% |
| Month 3 | 81% | 61% | 46% | 49% |
| Month 4 | 84% | 64% | 52% | 51% |
These numbers are illustrative.
The value of the table is that it shows how prompt-family visibility can be tracked over time.
Instead of monitoring only one overall figure, the business can see whether specific visibility gaps are becoming smaller, larger or more variable.
Measuring Change Without Misinterpreting It
Longitudinal analysis should distinguish several possibilities.
Improvement
Observed visibility increases in the same prompt family under comparable conditions.
Decline
Observed visibility decreases under comparable conditions.
Redistribution
Visibility decreases in one category while increasing in another.
Volatility
Results fluctuate without a clear directional trend.
Measurement expansion
The apparent change occurs because the prompt universe was expanded.
These categories should not be collapsed into a single “visibility up/down” label.
How VEM Can Help Investigate Persistent Gaps
Suppose repeated AVM experiments show:
General AI SEO prompts: strong
Enterprise AI SEO prompts: weak
Enterprise GEO prompts: weak
Enterprise AI visibility prompts: weak
The repetition suggests a contextual pattern.
Now VEM-oriented analysis can examine the entity relationships surrounding the target brand.
Questions might include:
- Is the brand clearly associated with enterprise services?
- Is enterprise expertise consistently represented?
- Are relevant services connected to the brand?
- Are industry relationships clearly established?
- Are geographic relationships consistent?
- Do third-party sources reinforce those relationships?
- Are descriptions of the company consistent across important sources?
The purpose is not to assume that the answer is “missing entity signals.”
The purpose is to create a testable entity hypothesis.
Entity Fragmentation as a Potential Diagnostic
One possible explanation for inconsistent AI visibility is entity fragmentation.
Imagine that different sources describe the same organization in substantially different ways.
One source describes it as:
an SEO agency
Another as:
a digital marketing company
Another as:
an AI technology provider
Another emphasizes:
GEO and AI search
The organization may still be perfectly understandable to humans.
However, from an entity-analysis perspective, the surrounding semantic representation is less uniform.
If AVM testing simultaneously shows inconsistent visibility for AI-search-related prompts, the two observations can be investigated together.
That does not prove that fragmentation caused the AVM pattern.
It provides a reason to examine the relationship.
Entity-Context Gaps
Another possibility is an incomplete relationship between an entity and a context.
For example:
Brand → AI SEO
may be strongly represented.
But:
Brand → AI SEO → SaaS
may be less strongly represented.
Or:
Brand → GEO
may be established.
But:
Brand → GEO → Enterprise
may have weaker contextual support.
Prompt diversity can expose the difference.
VEM analysis can then investigate whether the relevant relationships are sufficiently represented across the brand’s entity ecosystem.
The AVM–VEM Diagnostic Loop
At this stage, the relationship can be expressed as a practical workflow.
Stage 1: Prompt Diversity
Construct a representative set of relevant prompts.
↓
Stage 2: AI Testing
Run those prompts under documented conditions.
↓
Stage 3: AVM Analysis
Measure observable visibility signals.
↓
Stage 4: Gap Detection
Identify prompt families with materially different patterns.
↓
Stage 5: Validation
Repeat and verify the pattern.
↓
Stage 6: VEM Investigation
Examine relevant entity and semantic relationships.
↓
Stage 7: Optimization Hypothesis
Develop a specific explanation and intervention.
↓
Stage 8: Retesting
Run the same and expanded prompts again.
This creates a continuous feedback loop.
What Businesses Should Do With a Detected Gap
A detected gap should not automatically lead to more content.
That is one of the most important practical lessons.
First identify the type of gap.
If the gap is informational
Investigate topical coverage and source representation.
If the gap is commercial
Investigate whether the brand is sufficiently represented in provider-selection contexts.
If the gap is recommendation-based
Investigate recommendation relevance, competitive context and supporting evidence.
If the gap is citation-based
Investigate the availability and consistency of authoritative supporting sources.
If the gap is geographic
Investigate geographic relevance and market representation.
If the gap is industry-specific
Investigate industry-specific expertise and entity relationships.
If the gap is entity-based
Investigate semantic relationships and entity consistency.
The intervention should therefore follow the diagnosis.
Why More Content Is Not Always the Answer
AI visibility problems are sometimes treated as content-volume problems.
A business discovers that it does not appear for a particular prompt and immediately produces another article.
That may not address the underlying issue.
The missing visibility could instead relate to:
- entity ambiguity
- insufficient third-party references
- inconsistent business descriptions
- competitive context
- weak service associations
- geographical relevance
- lack of evidence
- provider-specific retrieval behavior
Prompt diversity helps determine what kind of problem is actually being observed before an optimization response is selected.
How to Operationalize Prompt Diversity
A practical AI visibility program can operate at several frequencies.
Monthly Core Monitoring
Run the stable core prompt set.
The objective is longitudinal monitoring.
Quarterly Expanded Testing
Run the larger diversified set.
The objective is to identify emerging gaps.
Event-Based Testing
Run targeted tests after significant changes.
Examples:
- website migration
- rebrand
- acquisition
- new service
- new geography
- major positioning change
Research Testing
Conduct larger experiments when investigating a specific hypothesis.
For example:
Does enterprise contextualization affect the brand’s AI recommendation visibility?
That experiment could contain a dedicated prompt family specifically designed to investigate the question.
Creating a Prompt Governance System
Large-scale prompt testing can become difficult to manage.
A prompt governance system can prevent the dataset from becoming inconsistent.
Every prompt should have:
- unique ID
- exact wording
- intent
- category
- semantic family
- audience
- industry
- geography
- commercial status
- entity context
- date created
- last tested
- status
Prompts can then be classified as:
Core
Active
Experimental
Retired
This provides version control for the research dataset.
Prompt Versioning
Prompt wording should not be changed casually.
If a core prompt changes from:
Which are the best AI SEO companies?
to:
Which AI search optimization companies are best for enterprise businesses?
the research variable has changed substantially.
That should be treated as a new prompt rather than silently replacing the old one.
Versioning allows researchers to preserve historical comparability.
Building a Prompt-Level Data Record
A useful database structure can look like this:
| Field | Example |
| Prompt ID | COM-014 |
| Prompt family | Commercial |
| Intent | Provider selection |
| Context | Enterprise |
| Geography | Global |
| Provider | AI system |
| Model | Documented model |
| Test date | Recorded date |
| Brand presence | Yes |
| Citation | Yes |
| Recommendation | Yes |
| Position | 2 |
| Competitors | Recorded |
| Notes | Recorded |
This creates a reusable research dataset.
Over time, that dataset can support deeper analysis.
The Complete Prompt Diversity Experiment Checklist
A checklist is useful because experimental quality often depends on small procedural details.
Research Design Checklist
- Define the research question
- Define the target entity
- Define the search territory
- Define relevant services
- Define relevant audiences
- Define relevant industries
- Define relevant geographies
- Define relevant competitors
- Define the baseline
- Define the diversified test set
- Define the experimental period
- Define the AI providers to be tested
Prompt Construction Checklist
- Create baseline prompts
- Create lexical variations
- Create semantic variations
- Create informational prompts
- Create commercial prompts
- Create recommendation prompts
- Create comparative prompts
- Create industry prompts
- Create audience prompts
- Create geographic prompts
- Create service-specific prompts
- Create problem-based prompts
- Create competitive prompts
- Create entity-context prompts
- Remove irrelevant prompts
- Remove unnecessary duplicates
- Assign every prompt to a family
Testing Checklist
- Record the exact prompt
- Record provider
- Record model where available
- Record date
- Record location where relevant
- Record session conditions where relevant
- Preserve the complete response
- Record brand presence
- Record citation
- Record position
- Record recommendation
- Record competitors
- Record unusual output patterns
Analysis Checklist
- Calculate observed presence
- Calculate citation observations
- Calculate recommendation observations
- Analyze position
- Group results by prompt family
- Compare baseline and diversified results
- Examine prompt sensitivity
- Examine competitive differences
- Examine geographic differences
- Examine industry differences
- Examine audience differences
- Identify recurring gaps
- Validate suspected gaps
- Separate observation from interpretation
- Avoid unsupported causal claims
VEM Investigation Checklist
- Review brand-to-service relationships
- Review brand-to-industry relationships
- Review brand-to-location relationships
- Review brand-to-expertise relationships
- Review relevant people/entities
- Review semantic consistency
- Review entity completeness
- Review conflicting descriptions
- Review potential entity fragmentation
- Identify missing contextual relationships
- Develop a testable hypothesis
Reporting Checklist
- Document methodology
- Explain prompt selection
- Explain prompt diversity
- Show prompt-family structure
- Report test conditions
- Show relevant observations
- Separate illustrative data from actual data
- Explain limitations
- Avoid universal claims
- Provide actionable interpretation
- Establish a retesting schedule
What Prompt Diversity Cannot Tell You
A strong experiment also needs to define its boundaries.
Prompt testing provides observational evidence about AI-generated responses.
It does not provide direct access to the internal mechanisms that produced those responses.
It Cannot Reveal Proprietary Model Weights
An external visibility test cannot tell you exactly how a model internally represents a brand.
It observes outputs.
It does not inspect model parameters.
It Cannot Establish Exact Causality
If visibility increases after a website change, that does not automatically prove that the website change caused the increase.
Other variables may have changed.
The appropriate language is:
“Visibility increased following the change.”
not automatically:
“The change caused visibility to increase.”
It Cannot Guarantee Permanent Visibility
AI systems change.
Models change.
Retrieval systems change.
Sources change.
The web changes.
Therefore, a positive result represents visibility under the tested conditions and time period.
It is not a permanent guarantee.
It Cannot Predict Every Future AI Answer
A prompt set is a sample.
It cannot represent every possible future user question.
That is why prompt diversity improves coverage without eliminating uncertainty.
It Cannot Treat Every AI Provider as Identical
Different systems can produce different answers.
Cross-provider testing can reveal those differences.
It cannot assume that one provider’s behavior represents every AI environment.
Why Experimental Transparency Matters
If an article claims to report an AVM experiment, readers should be able to understand how the experiment was conducted.
At minimum, document:
- number of prompts
- prompt categories
- testing period
- AI environments tested
- relevant conditions
- measurement fields
- interpretation methodology
- limitations
If actual data cannot be published, explain why.
Do not replace missing data with invented numbers.
For an agency publishing original AI-search research, methodological transparency can be more valuable than a dramatic headline result.
The Difference Between a Research Experiment and an AVM Audit
These terms should also be kept distinct.
An AVM audit generally has a business-specific objective:
Evaluate this brand’s current AI visibility.
An AVM experiment has a research objective:
Test whether a particular measurement variable changes under controlled conditions.
For example:
Audit
What is this company’s current AI visibility?
Experiment
Does increasing prompt diversity reveal visibility differences that a narrow prompt set does not capture?
The experiment is therefore testing the measurement methodology itself.
That distinction makes the article more technically interesting.
Prompt Diversity Is a Sampling Problem
At its core, this research is partly a sampling problem.
The broader AI search landscape contains many possible ways of expressing a need.
A measurement system can only test a subset.
The question therefore becomes:
How representative is the subset?
A prompt set can be:
- small but focused
- large but repetitive
- broad but poorly controlled
- diverse and well structured
The final option is generally the most useful for diagnostic research.
But even a well-designed prompt set remains a sample.
It should not be presented as a complete representation of every possible AI interaction.
From a Single Score to a Visibility Distribution
This is one of the most important conceptual implications of the experiment.
Traditional reporting often asks for:
What is the AI visibility score?
Prompt diversity suggests an additional question:
What is the distribution of visibility across relevant contexts?
Imagine:
Overall observed visibility: 65%
That number becomes much more informative when accompanied by:
- informational: 82%
- commercial: 61%
- enterprise: 43%
- competitive: 39%
- geographic: 74%
- service-specific: 57%
Now the business knows where the measurement is concentrated.
This is why prompt diversity can increase the resolution of AI visibility analysis.
From Visibility Score to Visibility Profile
A mature AI visibility report can therefore contain two layers.
Aggregate layer
A high-level AVM measurement.
Diagnostic layer
A breakdown by:
- prompt family
- intent
- industry
- geography
- audience
- service
- competition
- entity context
- provider
The aggregate layer provides a summary.
The diagnostic layer provides the context needed to interpret the summary.
Neither needs to replace the other.
The Four Most Useful Questions After Every AVM Test
After collecting the results, ask:
1. Where is the brand visible?
Identify strong prompt families.
2. Where is the brand not visible?
Identify weak prompt families.
3. What distinguishes those prompt families?
Look at:
- intent
- context
- entities
- competition
- geography
- industry
4. Can the pattern be reproduced?
Repeat relevant prompts before drawing stronger conclusions.
This four-question process can turn an AI visibility report into a diagnostic exercise.
When Prompt Diversity Reveals a Real Opportunity
Suppose a brand consistently performs well for:
“What is AI search optimization?”
but poorly for:
“Which AI search optimization provider should an enterprise choose?”
The opportunity may not be simply “write more about AI search optimization.”
The business already has topical visibility.
The more specific question is:
Why does informational recognition not consistently translate into commercial recommendation visibility?
That question can lead to investigation of:
- provider positioning
- evidence
- commercial context
- enterprise relevance
- entity relationships
- competitive signals
This is a much more precise optimization problem.
When Prompt Diversity Reveals No Meaningful Gap
The opposite outcome is equally valuable.
Suppose the diversified test produces:
- strong general visibility
- strong commercial visibility
- strong recommendation visibility
- strong industry visibility
- strong geographic visibility
- consistent cross-provider observations
Then prompt diversification has done its job.
It has provided evidence that the initial measurement was not heavily dependent on a narrow prompt formulation.
The result does not prove universal visibility.
It increases confidence in the observed coverage of the tested search territory.
The Role of Prompt Diversity in GEO and AI Search Optimization
Generative Engine Optimization focuses on improving a brand’s ability to appear and be represented in AI-generated discovery environments.
Prompt diversity adds a measurement perspective.
Instead of optimizing for a single formulation:
“best AI SEO companies”
the strategy can investigate a wider set of relevant user expressions.
That includes:
- questions
- recommendations
- comparisons
- problems
- industries
- audiences
- locations
- service combinations
This creates a more realistic representation of how users can approach a category through conversational AI.
Why This Matters for Enterprise Brands
Enterprise brands have particularly complex search territories.
A single organization may have:
- multiple products
- multiple service categories
- multiple markets
- multiple industries
- multiple brands
- subsidiaries
- founders and executives
- regional entities
- technical solutions
- different buyer personas
A single prompt set cannot adequately represent all of those relationships.
Prompt diversity provides a framework for testing different portions of that landscape systematically.
For enterprise AI search programs, the objective should therefore be to build a modular prompt universe, not a static list of generic questions.
A Practical Enterprise Prompt Architecture
An enterprise test suite could be organized as:
Brand prompts
↓
Service prompts
↓
Industry prompts
↓
Audience prompts
↓
Geographic prompts
↓
Problem prompts
↓
Competitive prompts
↓
Entity prompts
Each layer answers a different question.
The resulting dataset can then be connected to an AVM reporting system.
The AI Visibility Regression Cycle
For ongoing measurement, the workflow can become:
Baseline
→ test
→ AVM measurement
→ identify gaps
→ VEM/entity investigation
→ implement change
→ wait for an appropriate observation period
→ retest
→ compare
→ update the prompt universe
→ repeat
This creates a longitudinal research program rather than a one-time AI visibility snapshot.
Key Findings From the AVM Experiment
The central research question was:
Can prompt diversity reveal hidden AI visibility gaps?
The experiment framework supports a qualified answer:
Yes, controlled prompt diversity can reveal visibility differences that a narrow prompt set may not expose.
But the important qualification is that prompt diversity does not magically make every measurement “accurate.”
Its value comes from expanding diagnostic coverage.
Several findings follow from that principle.
Finding 1: A Narrow Prompt Set Can Hide Contextual Differences
If all prompts occupy the same semantic territory, the resulting visibility measurement may provide limited information about other relevant contexts.
A brand can look consistently visible within that sample while performing differently elsewhere.
Finding 2: Prompt Diversity Is More Valuable When It Is Structured
Random prompt generation is not the goal.
Meaningful variation across intent, context, audience, industry, geography, competition and entity relationships provides more useful information.
Finding 3: Mention Visibility Is Not Recommendation Visibility
A brand can be recognized without being recommended.
Therefore, AI visibility analysis should distinguish between different observable response signals.
Finding 4: Aggregate Visibility Can Hide Localized Gaps
A strong overall result can coexist with weaker performance in:
- enterprise prompts
- commercial prompts
- competitive prompts
- specific industries
- specific geographies
Prompt-family analysis exposes these differences.
Finding 5: Prompt Sensitivity Is Itself Useful Information
If small but meaningful changes in prompt context produce major differences in visibility, that pattern deserves investigation.
It can indicate that the brand’s AI visibility is highly context-dependent.
It does not, by itself, identify the reason.
Finding 6: AVM and VEM Answer Different Diagnostic Questions
AVM can be used to investigate observable AI visibility.
VEM can be used to investigate the entity and semantic context surrounding a brand.
The two can therefore form a diagnostic loop:
Measure → identify → investigate → optimize → retest.
The Complete AVM–VEM Framework
The entire approach can now be condensed into a practical model.
Layer 1: Search Landscape
Identify the relevant topics, intents, audiences, industries, locations and competitors.
Layer 2: Prompt Diversity
Translate that landscape into a structured prompt universe.
Layer 3: AI Observation
Run the prompts under documented conditions.
Layer 4: AVM Measurement
Evaluate observable visibility signals.
Layer 5: Gap Analysis
Identify differences between prompt families.
Layer 6: VEM Investigation
Examine relevant entity and semantic relationships.
Layer 7: Optimization
Develop targeted interventions based on the diagnosed gap.
Layer 8: Regression Testing
Repeat the experiment using stable and expanded prompts.
This transforms AI visibility from a one-time report into an iterative measurement system.
Best Practices for Reliable AI Visibility Experiments
A high-quality experiment should follow several principles.
Keep a Stable Baseline
Do not constantly replace your core prompts.
A stable baseline is essential for longitudinal comparison.
Expand Systematically
Add new prompts according to defined dimensions.
Do not add prompts randomly.
Preserve Exact Wording
Small changes can alter meaning.
Keep the original prompt record.
Classify Every Prompt
Every prompt should belong to a defined family.
Separate Observation From Interpretation
Record what happened before explaining why it happened.
Replicate Important Findings
Repeated patterns are more informative than isolated outputs.
Record Conditions
Document provider, model where available, date and relevant context.
Don’t Manufacture Gaps
A brand should not be expected to appear in every conceivable prompt.
Don’t Manufacture Results
Illustrative examples must remain clearly labeled.
Don’t Overinterpret Causality
An observed change following an optimization does not automatically establish that the optimization caused it.
A Practical Prompt Diversity Reporting Template
A final report can contain five sections.
Executive Measurement
Provide the high-level AVM observations.
Prompt Coverage
Show how many prompts were tested and how they were distributed.
Visibility Distribution
Show results by:
- intent
- industry
- geography
- audience
- service
- competitive context
Gap Analysis
Highlight materially different patterns.
Investigation and Next Steps
Connect validated patterns to potential VEM or broader AI-search investigations.
This makes the report useful for both technical teams and business decision-makers.
Prompt Diversity and AVM Experiment Checklist
Before publishing or executing an experiment, use the following final checklist.
Research
- Research question clearly defined
- Hypotheses documented
- Target entity defined
- Search territory defined
- Relevant business contexts defined
- Experimental boundaries established
Prompt Dataset
- Baseline prompts created
- Semantic variants created
- Intent variants created
- Commercial prompts included
- Recommendation prompts included
- Industry prompts included
- Geographic prompts included
- Audience prompts included
- Competitive prompts included
- Problem-based prompts included
- Entity-context prompts included
- Duplicate prompts removed
- Irrelevant prompts removed
- Prompt families assigned
Testing Conditions
- AI provider documented
- Model documented where available
- Test date recorded
- Relevant location recorded
- Session conditions documented
- Exact prompt preserved
- Complete response preserved
AVM Analysis
- Presence measured
- Citation measured
- Recommendation measured
- Position recorded
- Consistency evaluated
- Prompt-family results compared
- Provider-level differences examined
- Baseline compared with diversified testing
- Prompt sensitivity examined
Gap Validation
- Brand relevance confirmed
- Pattern replicated
- Prompt family checked
- Potential measurement artifacts investigated
- Temporal effects considered
- Provider differences considered
- No unsupported causal conclusion made
VEM Investigation
- Brand-service relationships reviewed
- Brand-industry relationships reviewed
- Brand-location relationships reviewed
- Brand-expertise relationships reviewed
- Entity consistency reviewed
- Potential fragmentation reviewed
- Missing semantic relationships investigated
- Hypotheses documented
Reporting
- Methodology disclosed
- Prompt sampling explained
- Actual and illustrative data separated
- Limitations documented
- Observations separated from interpretations
- Recommendations linked to findings
- Retesting plan established
Conclusion
AI visibility is not necessarily a single, stable condition that can be fully represented by asking one question repeatedly.
A brand can appear consistently when users use one formulation while becoming less visible when the same underlying need is expressed through another context. The difference can emerge when the prompt introduces a new industry, audience, geography, commercial objective, competitor, service requirement or entity relationship.
That does not mean every variation represents a ranking opportunity.
It means the visibility landscape is multidimensional.
Prompt diversity provides a way to investigate that landscape systematically.
The central value of the approach is not simply generating more prompts. It is constructing a controlled sample of relevant search situations and then examining how observable AI visibility changes across those situations.
An AVM experiment can therefore move beyond a simple question such as:
“Does the AI mention the brand?”
and investigate:
“In which relevant contexts does the AI mention the brand, cite it, recommend it, position it prominently and continue to recognize it consistently?”
That shift creates substantially more diagnostic information.
It can reveal an informational visibility gap that commercial prompts expose. It can uncover an enterprise gap hidden by general category searches. It can show that a brand is frequently mentioned but rarely recommended. It can reveal competitive displacement that never appears in open-category testing. It can identify geographic or industry-specific differences that disappear inside an aggregate figure.
Most importantly, it creates a disciplined pathway from observation to investigation.
Prompt diversity expands the measurement surface.
AVM identifies observable visibility patterns.
VEM can provide an entity-oriented framework for investigating relevant semantic relationships behind those patterns.
The result is not a promise of perfect measurement.
AI systems remain dynamic, and no external experiment can observe every possible prompt or reveal every internal mechanism behind an AI-generated response.
The objective is more practical and more defensible:
make AI visibility measurement more representative, more granular and more useful for decision-making.
For businesses investing in GEO, AEO, LLM visibility and AI search optimization, that distinction matters.
The future of AI visibility measurement is unlikely to be defined solely by asking whether a brand appears.
It will increasingly depend on understanding the conditions under which it appears, the conditions under which it disappears, the strength of the resulting signals, and whether those patterns remain consistent when the search environment changes.
That is where prompt diversity becomes more than a collection of alternative questions.
It becomes an experimental instrument for discovering the parts of AI visibility that a narrow measurement may never reveal.